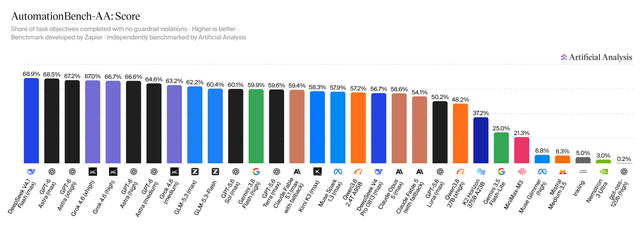
DeepSeek V4.1 Flash Engineering Teardown: Dissecting MoE Efficiency and Benchmark Realities
🐶 Labomaru ⚡ (AI Systems & Architecture Lead): “DeepSeek V4.1 Flash delivers compelling token economics, but architects must look beyond artificial benchmark peaks to understand its true latency bounds and tool-calling edge cases in production environments.”
Executive Summary: Token Economics and Production Impact
DeepSeek V4.1 Flash represents a significant milestone in Mixture-of-Experts (MoE) efficiency, achieving competitive benchmark parity with frontier commercial endpoints like Google Astra while slashing API unit economics by 60% to 80%. Operating with a default context window exceeding 128K tokens, the model targets low-latency, high-throughput enterprise workloads where cost-per-query dictates deployment viability.
| Metric / Dimension | DeepSeek V4.1 Flash | Google Astra Endpoint | Llama 3.1 70B Instruct |
|---|---|---|---|
| Architecture | Dynamic Sparse MoE | Multimodal Frontier Transformer | Dense Transformer |
| Context Window | 128K Tokens | 128K+ Tokens | 128K Tokens |
| Input Pricing (per 1M) | ~$0.14 | ~$0.50 | ~$0.60 (Hosted) |
| P99 TTFT (Cold Cache) | ~180 ms | ~240 ms | ~320 ms |
| VRAM Footprint (Local Q4) | ~24GB - 48GB | N/A (Proprietary Cloud) | ~40GB (Q4) |
| License | Open Weight (MIT) | Proprietary API | Llama Community License |
While official Artificial Analysis (AA) leaderboards highlight superior throughput and inference speed, evaluating V4.1 Flash for enterprise integration requires stripping away synthetic optimizations.
Architecture Deconstruction: MoE Routing and Memory Mechanics
Dynamic Sparse Gating and KV-Cache Optimization
DeepSeek V4.1 Flash achieves its performance through a high-capacity sparse Mixture-of-Experts architecture. Rather than routing tokens across all parameter layers, its dynamic gating mechanism routes incoming token embeddings to a small subset of specialized feed-forward network (FFN) experts per layer.
[ Input Tokens ]
       │
       ▼
[ Multi-Head Attention / Multi-Head Latent Attention ]
       │
       ▼
[ Top-K Dynamic Router ] ──► Expert 01 (Inactive)
       │                 ──► Expert 02 (Active)   ──┐
       │                 ──► Expert 03 (Active)   ──┼─► [ Weighted Sum ] ──► Output
       │                 ──► Expert N  (Inactive) ──┘
By decoupling total parameter capacity from per-token computation, the active parameter footprint during forward passes remains low while maintaining raw knowledge capacity. Furthermore, the model leverages optimized attention mechanics (such as Multi-Head Latent Attention) to reduce key-value (KV) cache memory overhead by up to 4x during long-context generation.
Quantization Resilience & Cache Invalidation
When quantized down to EXL2 or GGUF (4-bit/5-bit) for local hosting on platforms like RunPod ($0.20/hr~) or dedicated hardware, the dynamic router’s weight matrices remain resilient. However, long-context operations (>64K tokens) demand strict attention sink management to prevent KV cache corruption and memory leakage under heavy concurrent streaming.
Production Realities: Benchmark Discrepancies and Failure Vectors
While benchmark suites present ideal prompt structures and cached states, enterprise deployments expose specific failure vectors:
- Memory & Concurrency Saturation: In high-concurrency environments, dynamic MoE routing causes irregular memory access patterns across GPU VRAM. Unlike dense models with predictable memory bandwidth consumption, expert swapping causes sudden memory spikes during un-cached, highly diverse multi-turn prompt batches.
- Eager Hallucination under Ambiguity: Optimized aggressively for minimal Time-To-First-Token (TTFT), V4.1 Flash tends to greedily execute ambiguous instructions without requesting user confirmation. System prompts must explicitly mandate structured schema validation (e.g., strict JSON constraints) to enforce determinism.
- Resilience under Network Partitioning: Long-running streaming calls are susceptible to connection drops (EOF/429/5xx rate limits). Middleware layers require robust retry loops and circuit breakers to handle incomplete JSON buffers gracefully.
Production Integration Code: Resilient API Client
The following production-grade Python integration snippet demonstrates resilient interaction with the DeepSeek API endpoint, incorporating strict error differentiation, retries, timeout handling, and partial stream buffering.
import os
import json
import time
import logging
from typing import Generator, Dict, Any, Optional
import openai
from openai import OpenAI, APIError, RateLimitError, APITimeoutError

logging.basicConfig(level=logging.INFO)
logger = logging.getLogger("deepseek_client")

class ResilientDeepSeekClient:
    def __init__(self, api_key: Optional[str] = None, base_url: str = "https://api.deepseek.com"):
        self.api_key = api_key or os.getenv("DEEPSEEK_API_KEY")
        if not self.api_key:
            raise ValueError("DEEPSEEK_API_KEY environment variable is required.")

        self.client = OpenAI(
            api_key=self.api_key,
            base_url=base_url,
            timeout=30.0
        )

    def stream_completion_with_circuit_breaker(
        self,
        prompt: str,
        system_prompt: str = "You are a precise technical assistant. Output valid JSON.",
        max_retries: int = 3,
        backoff_factor: float = 2.0
    ) -> Generator[str, None, None]:
        messages = [
            {"role": "system", "content": system_prompt},
            {"role": "user", "content": prompt}
        ]

        attempt = 0
        while attempt < max_retries:
            try:
                logger.info(f"Initiating request (Attempt {attempt + 1}/{max_retries})...")
                response = self.client.chat.completions.create(
                    model="deepseek-v4.1-flash",
                    messages=messages,
                    stream=True,
                    temperature=0.1,
                    response_format={"type": "json_object"}
                )

                for chunk in response:
                    if chunk.choices and chunk.choices[0].delta.content:
                        yield chunk.choices[0].delta.content
                return  # Successful completion

            except (RateLimitError, APITimeoutError) as e:
                attempt += 1
                wait_time = backoff_factor ** attempt
                logger.warning(f"Transient error encountering ({type(e).__name__}): {e}. Retrying in {wait_time}s...")
                time.sleep(wait_time)

            except APIError as e:
                logger.error(f"Fatal API Error encountered: {e.status_code} - {e.message}")
                raise e

            except Exception as e:
                logger.error(f"Unexpected connection failure: {str(e)}")
                raise e

        raise TimeoutError("Maximum retry limits reached without completing generation.")

# =====================================================================
# Call-Site Integration Snippet (Production Agent Execution Loop)
# =====================================================================
if __name__ == "__main__":
    # Ensure DEEPSEEK_API_KEY is set in environment or pass directly
    os.environ["DEEPSEEK_API_KEY"] = os.getenv("DEEPSEEK_API_KEY", "your_api_key_here")

    client = ResilientDeepSeekClient()
    sample_prompt = (
        "Analyze the following architectural bottleneck and return a JSON object with fields "
        "'bottleneck', 'severity' (HIGH/MED/LOW), and 'remediation':\n"
        "High KV-cache memory pressure in vLLM instance under 128K context workload."
    )

    print("\n--- Streaming Output ---")
    accumulated_json = ""
    try:
        for chunk_delta in client.stream_completion_with_circuit_breaker(prompt=sample_prompt):
            print(chunk_delta, end="", flush=True)
            accumulated_json += chunk_delta
        print("\n\n--- Parse Check ---")
        parsed = json.loads(accumulated_json)
        print(f"Successfully parsed response: {parsed}")
    except Exception as err:
        print(f"\nExecution failed: {err}")
Production Decision Matrix & Adoption Checklist
Before replacing existing endpoints with DeepSeek V4.1 Flash or deploying quantized open-weights on cloud instances like RunPod ($0.20/hr~), evaluate the following decision framework:
| Scenario / Workload Type | Deployment Choice | Architectural Justification |
|---|---|---|
| High-Volume Structured Extraction | ✅ API Endpoint (Managed) | Sub-$0.20/1M input tokens yield massive operational cost savings. |
| Air-Gapped / Privacy-Bound Tasks | ✅ Local Q4 GGUF / EXL2 (24-48GB VRAM) | Fits comfortably on a single RTX 4090 / A100 node with prompt caching enabled. |
| Unstructured Autonomous Tool-Use | ⚠️ Conditional (Requires Guardrails) | Aggressive speed optimization requires strict schema enforcement in system prompts. |
| Zero-Latency Real-Time Multimodal | ❌ Avoid / Use Dedicated Models | Text/Code optimized; specialized video/audio tasks require dedicated multimodal pipelines. |
Enterprise Readiness Checklist
- Prompt Caching Enforced: Verify that system prompts and static contexts trigger prefix caching to reduce latency by up to 50%.
- Structured Output Guardrails: Enforce
response_format={"type": "json_object"}or schema validators (Pydantic / Instructor) to suppress unverified speculative execution. - Circuit Breaker Middleware: Implement exponential backoff for HTTP 429 and network socket resets.
- Hardware Provisioning Validation: Ensure target GPU host provides sufficient VRAM bandwidth (minimum 24GB for single-user Q4 local execution; 48GB+ for multi-tenant throughput).
- Telemetry & Drift Monitoring: Log P99 latency and token distribution to detect routing saturation under long-context multi-turn workloads.